Table of contents Show Hide
- What the status means
- Root cause: canonicals had the slash, links did not
- Slash or no slash
- Why a 301 alone falls short
- The fix, from link source to build check
- 1. One path helper
- 2. Structured data and text indexes
- 3. Rewrite links in the built HTML
- 4. A 301 fallback in the Cloudflare Worker
- 5. Build-time checks against regressions
- What changes in Search Console
- Summary
In Google Search Console’s page indexing report, “Alternate page with proper canonical tag” looks like a status you can ignore. When my site hit it, URL Inspection showed:
- User-declared canonical:
https://zengliangyi.com/en/blog/tag/tailwind-css/ - Google-selected canonical: same as user-declared
- Referring page:
https://zengliangyi.com/en/blog/tag/tailwind-css/
The canonical and the referring page look like the same address, so which URL was the alternate? The inspected URL was /en/blog/tag/tailwind-css without the trailing slash. Google crawled it, read a canonical pointing at the slash version, and classified it as an alternate. The referring page field says something more important: Google found that non-slash URL on my own site.
💡 Where to find the referring page in Search Console Click the affected URL in the report -> click Inspect URL -> expand the Discovery card -> check Referring page. This shows which page gave Googlebot the uncanonical link.
What the status means
The status tells you three things:
- Google crawled URL A;
- A’s canonical points at URL B;
- Google agreed, indexed B, and left A out of results.
From an indexing point of view the canonical works and B is indexed. The problem is how many A URLs exist and where they come from. A few old external links are harmless. If every page’s navigation and breadcrumbs emit A, Google finds a new batch of duplicates with every crawl, crawl budget goes to duplicates, and the alternate-page count keeps growing.
Root cause: canonicals had the slash, links did not
The site runs on Astro and deploys to Cloudflare Workers. URL formats were inconsistent across the output:
| Location | Format |
|---|---|
| Build output | /blog/tag/css/index.html (Astro default build.format: 'directory') |
<link rel="canonical"> |
trailing slash |
sitemap-0.xml |
trailing slash |
<a href> in pages (nav, tags, pagination) |
no slash, e.g. /en/blog/tag/tailwind-css |
BreadcrumbList JSON-LD item |
no slash |
BlogPosting author URL, llms.txt |
no slash |
Astro’s trailingSlash defaults to 'ignore', so both forms reach the same page and nothing fails during development. Components build paths with helpers such as localizedPath('/about', locale), which return the non-slash form. The sitemap and canonical come from the build output and carry the slash. Each side was correct on its own; together they declared one URL and linked another.
After the build, the site’s HTML contained 14,172 internal page links missing the trailing slash.
Slash or no slash
Google has no preference and only asks for consistency. The slash form won because of the output structure:
- Astro’s directory build emits
/slug/index.html, so slash URLs map directly to files; - canonicals and the sitemap already used the slash, so only links needed to change;
- indexed canonical URLs stay the same, and Google does not need to reselect them.
Going the other way would mean changing build.format, canonicals, the sitemap, and already indexed URLs at once.
Why a 301 alone falls short
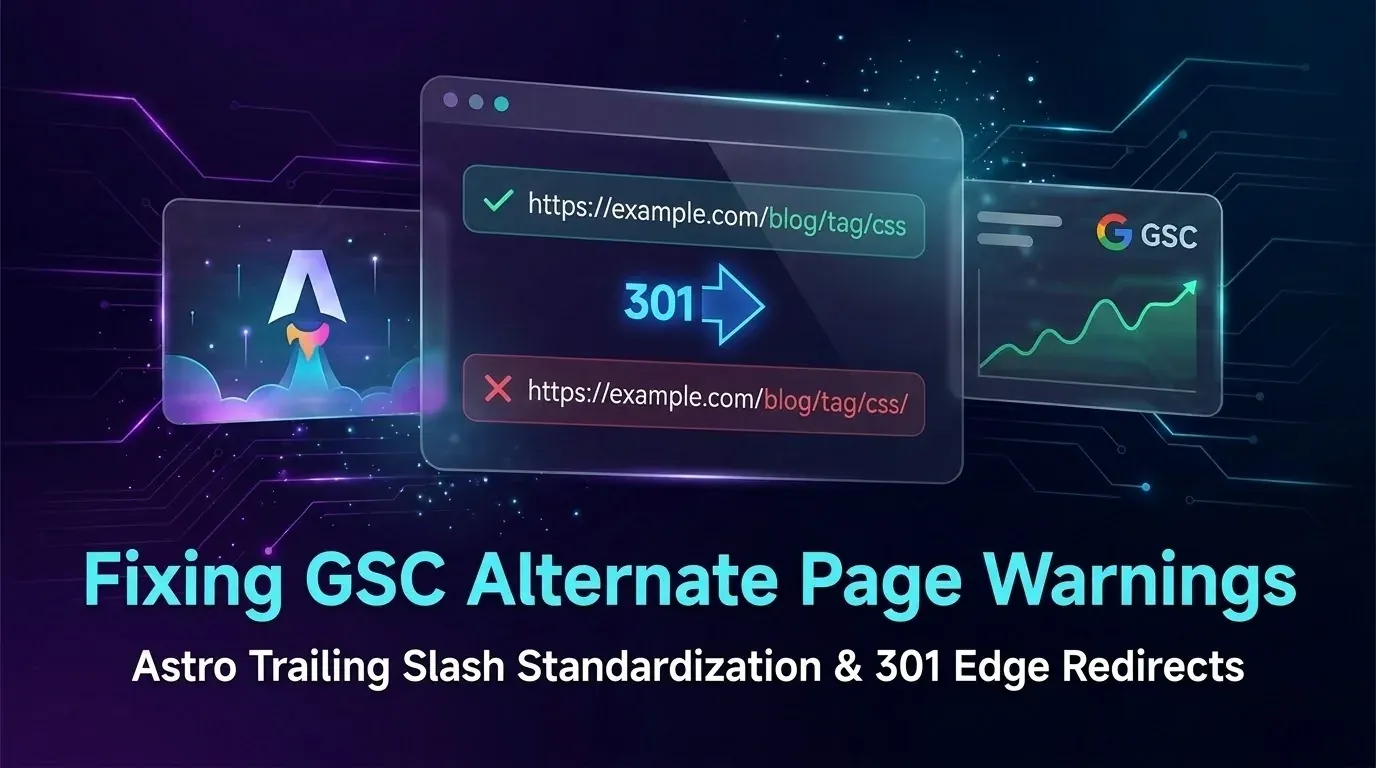
The obvious fix is a 301 at the edge from the non-slash URL to the slash URL. Google would consolidate signals, but if internal links stay unchanged:
- every crawl of an internal link costs two requests, the old URL and the redirect target;
- Search Console trades “Alternate page” entries for a long list of “Page with redirect”;
- every internal click adds a redirect round trip for users.
So internal links must point at the canonical URL directly, and the 301 only handles external links and URLs Google already knows.
The fix, from link source to build check
1. One path helper
src/lib/canonical-path.ts appends a slash only to internal page paths. It skips static files, APIs, and external URLs, and keeps query strings and fragments:
const FILE_EXTENSION_RE =
  /\.(?:xml|json|txt|md|html|htm|png|jpe?g|webp|gif|svg|ico|webmanifest|woff2?|ttf|otf|eot|css|js|mjs|cjs|map|pdf|zip|wasm)$/i;

const NON_PAGE_PREFIX_RE = /^\/(?:api|\.well-known|_astro|images|assets)(?:\/|$)/;

export function ensureTrailingSlash(href: string): string {
  if (!href || !href.startsWith('/') || href.startsWith('//')) return href;
  // Split off #hash and ?query, then test only the pathname
  // '/about#faq' -> '/about/#faq', '/rss.xml' stays unchanged
  // ...
}
Paths like /.well-known/api-catalog have no extension but are not pages. The prefix list excludes them so they do not gain a slash and return 404.
2. Structured data and text indexes
The breadcrumb component renders visible links and BreadcrumbList JSON-LD, and both go through ensureTrailingSlash:
const schemaItems = items.map((item) => ({
  name: item.label,
  url: new URL(ensureTrailingSlash(item.href ?? Astro.url.pathname), siteConfig.url).toString(),
}));
The BlogPosting author URL and the post and project URLs in llms.txt get the same treatment. Search engines discover URLs from structured data too, so fixing <a href> alone is not enough.
3. Rewrite links in the built HTML
Navigation, tag clouds, and pagination live in dozens of components, and fixing each by hand invites misses. The site already had an integration that walks every HTML file in astro:build:done to produce Markdown versions for AI agents, so the rewrite happens there:
for (const htmlPath of htmlFiles) {
  const rawHtml = await readFile(htmlPath, 'utf8');
  const htmlContent = normalizeInternalPageHrefs(rawHtml);
  if (htmlContent !== rawHtml) {
    await writeFile(htmlPath, htmlContent, 'utf8');
  }
  // Markdown is then generated from the normalized HTML
}
A future component that hard-codes a non-slash link still ships a corrected link, and the Markdown versions stay consistent.
4. A 301 fallback in the Cloudflare Worker
wrangler.toml sets run_worker_first = true, so every request passes through the Worker entry. The 301 lives in that entry function instead of a dashboard redirect rule, which keeps it versioned with the code:
if (
  (request.method === 'GET' || request.method === 'HEAD') &&
  url.pathname !== '/' &&
  !url.pathname.endsWith('/') &&
  !FILE_EXTENSION_RE.test(url.pathname) &&
  !NON_PAGE_PREFIX_RE.test(url.pathname)
) {
  return Response.redirect(url.origin + url.pathname + '/' + url.search, 301);
}
Verified after deployment:
$ curl -sI https://zengliangyi.com/blog
HTTP/2 301
location: https://zengliangyi.com/blog/
5. Build-time checks against regressions
A one-time fix does not stop a future component from emitting non-slash links. scripts/verify-build.mjs gained two checks that fail the build on any violation:
- every
BreadcrumbListitemmust end with/; - every internal page
<a href>in the HTML must end with/.
Following the repository’s convention, the check ran first against the unfixed output to confirm it fails. It reported the non-slash breadcrumb items and all 14,172 internal links. After the fix and a rebuild, it passed. A check that has only run against working output proves nothing about catching the problem.
What changes in Search Console
- New pages: no non-slash links exist on the site, so Google stops discovering duplicates there;
- Known old URLs: on recrawl they return 301 and move from “Alternate page” to “Page with redirect”, which is expected;
- When reviewing the report, switch the filter from “All known pages” to “All submitted pages” to see only sitemap URLs. Redirects and alternates should not appear there.
http:// and www. URLs that redirect to the https:// apex appear under “Page with redirect” for the same reason and need no action.
Summary
“Alternate page with proper canonical tag” shows that canonicals work, and also that the site is feeding Google duplicate URLs. The order of work:
- Pick one URL format based on the build output;
- Use the canonical URL directly in internal links, structured data, and text indexes;
- Add an edge 301 for external links;
- Check the output at build time so it does not regress.
After the fix, active submission helps search engines recrawl sooner; see Google Indexing in Astro: Incremental Cache-Driven Submissions. The same post-build artifact verification pattern also catches silent metadata 404s when precompiling Astro WebP images on Cloudflare Workers.